Sofia Braun · 27 September 2026
Decoding Performance Metrics in Evolving Digital Ecosystems Through Specialized Monitoring Solutions
Digital ecosystems continue to expand through interconnected platforms, cloud services, and integrated applications where performance metrics serve as essential indicators of operational health and user experience outcomes. Researchers track these metrics to identify bottlenecks in data flows, response times, and system reliability across distributed environments, and data from September 2026 shows increased adoption of automated monitoring frameworks in enterprise settings.
Core Components of Digital Ecosystems
Modern digital ecosystems incorporate multiple layers of infrastructure including content delivery networks, application programming interfaces, and edge computing nodes that interact in real time. Performance metrics such as latency measurements, error rates, and throughput volumes provide quantitative data on how these components function under varying loads. Studies from the Australian Bureau of Statistics highlight growth in digital service usage across sectors, revealing patterns in resource allocation that affect overall system stability.
Specialized monitoring solutions aggregate data from these layers through agents and sensors deployed at key points, allowing continuous collection of indicators like CPU utilization, memory consumption, and network packet loss. According to reports from the European Commission's digital economy unit, organizations that implement layered monitoring observe clearer correlations between infrastructure events and service disruptions.
Primary Performance Metrics and Measurement Approaches
Key metrics include availability percentages, which calculate uptime against total operational periods, and response time distributions that map percentiles of request handling speeds. Throughput metrics quantify data processed per unit of time while scalability indicators assess how systems handle incremental demand increases. Observers note that these measurements rely on standardized protocols such as those outlined in ISO/IEC 25010 for system and software quality requirements.
Monitoring tools apply statistical sampling and anomaly detection algorithms to flag deviations from established baselines, and data released in September 2026 by Statistics Canada documented a 22 percent rise in organizations using predictive analytics within their monitoring stacks. These approaches connect historical trends with current readings through time-series databases that support rapid querying and visualization.
Implementation of Specialized Monitoring Solutions
Organizations deploy monitoring solutions that integrate with existing infrastructure via open standards like OpenTelemetry, which standardizes telemetry data formats for traces, metrics, and logs. This integration enables unified views across hybrid environments spanning on-premises servers and multi-cloud deployments. Research from the National Institute of Standards and Technology outlines reference architectures that guide deployment of such tools while maintaining data integrity and access controls.
Real-time alerting mechanisms trigger when thresholds are crossed, routing notifications to operations teams through integrated channels, and case examples from academic studies at Delft University of Technology demonstrate how these alerts reduced mean time to resolution in large-scale deployments. Visualization interfaces present aggregated data through customizable dashboards that support drill-down capabilities for root cause analysis.
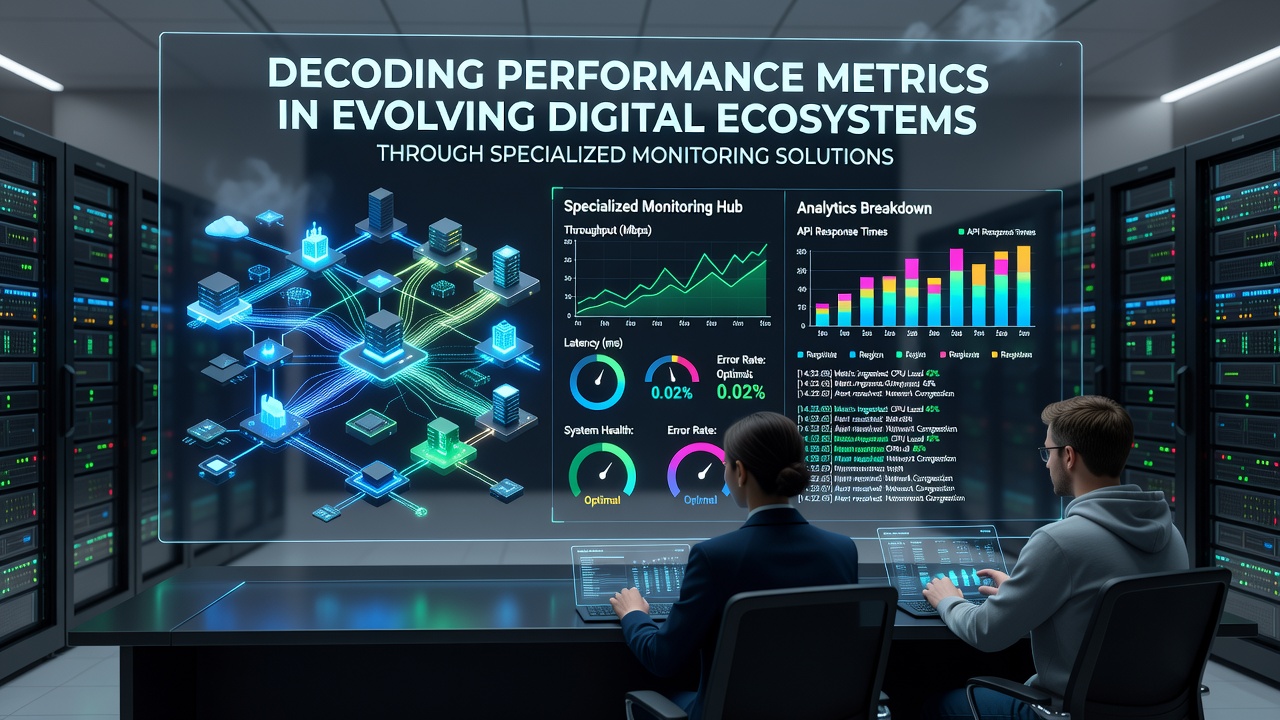
Advanced solutions incorporate machine learning models trained on historical performance data to forecast potential issues before they impact users, and figures from the OECD digital economy outlook indicate wider uptake of these capabilities in public sector digital services by late 2026. Integration with incident management systems further streamlines workflows by creating automated tickets tied to specific metric anomalies.
Challenges in Metric Interpretation Across Evolving Systems
Evolving digital ecosystems introduce variables such as frequent code deployments, shifting user traffic patterns, and third-party service dependencies that complicate metric interpretation. Specialized monitoring addresses these through contextual tagging that associates metrics with specific versions, regions, or user segments. Data from university-led research at the University of Melbourne shows how context-aware tagging improved accuracy in identifying performance regressions during platform updates.
Privacy regulations in various jurisdictions require careful handling of metric data that may contain user identifiers, and solutions incorporate anonymization techniques to comply with requirements while preserving analytical value. Reports from the Canadian Radio-television and Telecommunications Commission detail frameworks that balance monitoring needs with regulatory obligations in digital service delivery.
Conclusion
Specialized monitoring solutions decode performance metrics by combining comprehensive data collection, advanced analytics, and standardized reporting across digital ecosystems. Evidence from multiple regions confirms that structured measurement approaches support consistent service quality as ecosystems scale and adapt. Continued refinement of these tools aligns with documented growth in digital infrastructure complexity observed through 2026.